
Download the matching self-contained notebook · Read the notebook preview
What you will build
LoRA keeps an existing matrix W fixed and learns a correction through two smaller matrices A and B. Before using the neural router, we will multiply a two-by-two example so the shapes and transposes are concrete.
The same complete file then applies LoRA to the router’s encoder, trains the added matrices, and compares the two-path calculation with a merged matrix. Every helper used in that experiment is defined below; there is no ft_lab import.
By the end: Calculate, train, and merge a low-rank weight correction.
- What you will build
- What you need before starting
- Understand the idea before the code
- A picture of this part's idea
- Create the lesson folder
- Complete code for this article
- Run it and compare the result
- Walk through what just happened
- Change one thing yourself
- If your result is different
- What you can now explain
What you need before starting
You need basic Python: variables, functions, dictionaries, loops, and imports. When this lesson introduces a class or a library-specific term, its role is explained below.
Use Python 3.12. These examples were executed on Windows with Python 3.12.4. Use the shown interpreter consistently when installing packages and running code. This is an original small CPU teaching experiment, not a downloaded general-purpose LLM.
You do not need to run an earlier article to make this part execute. The complete files and data used here are supplied below. The series order is for learning the ideas progressively.
Understand the idea before the code
A matrix is a rectangular table of numbers. Its shape is rows by columns. Matrix multiplication, written @ in Python, combines matching dimensions; it is not element-by-element multiplication. A transpose, written .T, swaps rows and columns.
For a linear layer, W contains the original weights. Delta means change, so delta_W is a proposed change to those weights. LoRA, Low-Rank Adaptation, learns that change using two smaller matrices instead of updating all entries of W independently.
Rank describes the number of independent directions a matrix can express. You can think of low rank as building a correction from a small number of reusable patterns. It does not mean the model's quality ranking. With rank 1, an outer product of one column and one row produces a whole update matrix from one such pattern.
A has shape [rank, input_width]; B has shape [output_width, rank]. Therefore B @ A has the same [output_width, input_width] shape as W. alpha/rank is a numeric scale applied to that correction. alpha is an adjustable configuration value, not a learned token or a probability.
A picture of this part's idea
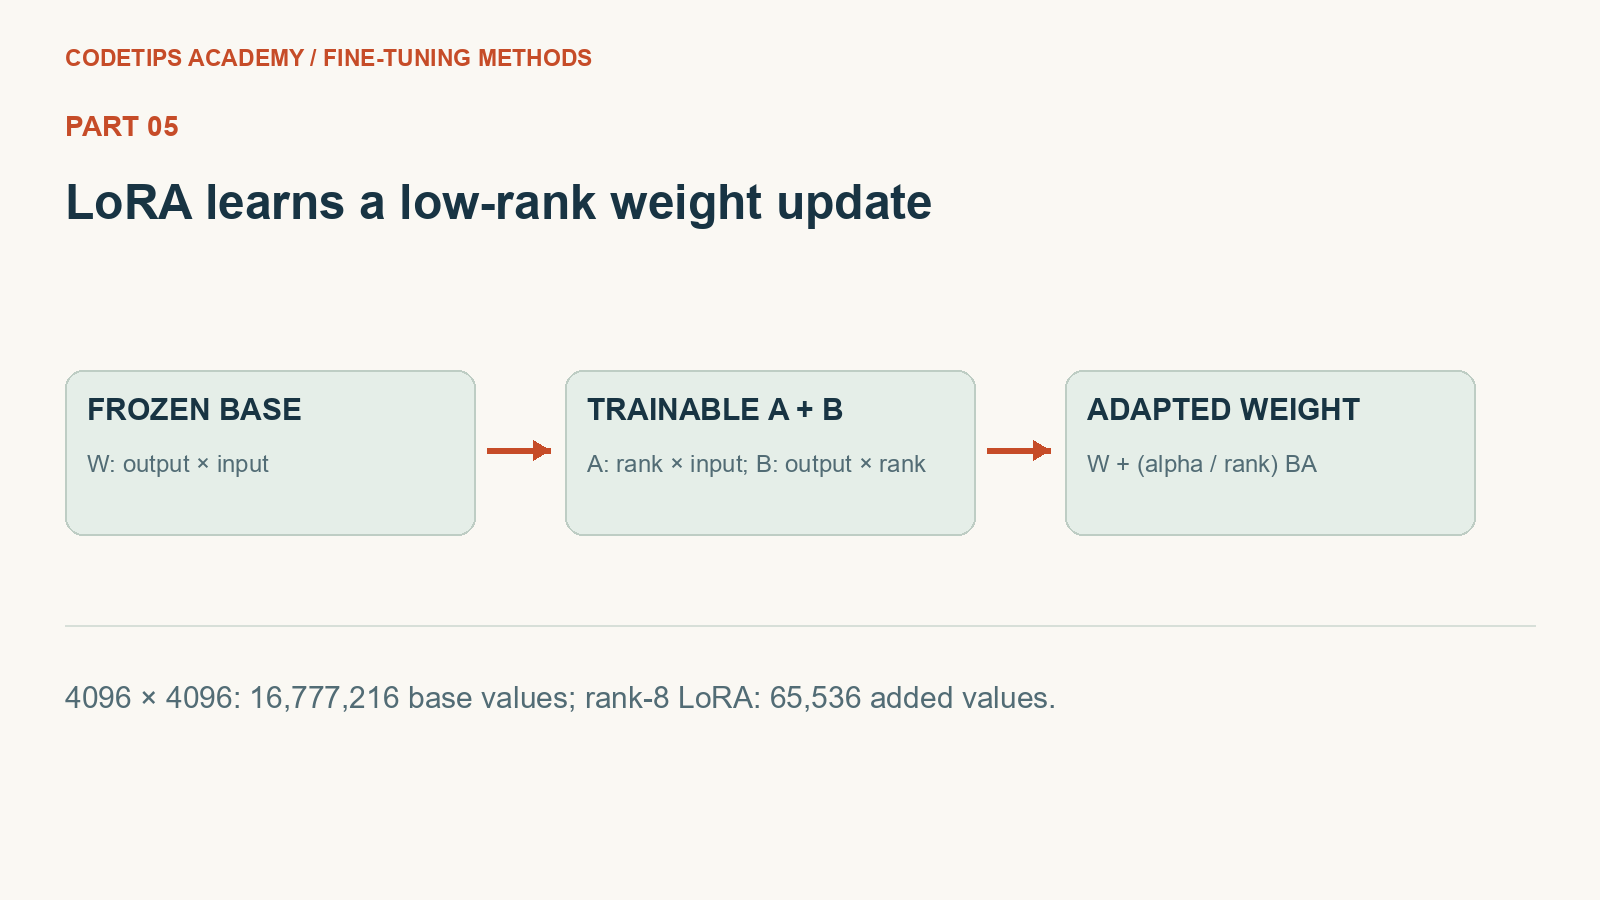
This picture introduces the mechanism. The numbers and assertions in the program below are the actual experiment.
Create the lesson folder
Create this folder and keep the filenames exactly as shown. In particular, a local module is an ordinary file beside the program, not an extra package you must guess how to install.
lesson-folder/
  lesson.py
  requirements.txt
Save requirements.txt
These are the external Python packages for this lesson. The local files above are included in the article; they are not pip packages.
torch==2.2.2
numpy==1.26.4
matplotlib==3.9.1
python -m venv .venv
.venv\Scripts\python.exe -m pip install -r requirements.txt
On Linux/macOS, use python3 -m venv .venv and .venv/bin/python -m pip install -r requirements.txt. Installation requires internet access. The default examples do not call a paid API.
Complete code for this article
Save this complete file as lesson.py
This is the complete program, including imports, data, function definitions, and the entry point.
import copy
import re
import torch
from torch import nn
from torch.nn import functional as F

LABELS = ["python", "linux", "iot"]

GROUPS = [
    ("python", ["python", "list", "dictionary", "function", "script", "package"]),
    ("linux", ["linux", "shell", "permission", "service", "process", "terminal"]),
    ("iot", ["esp32", "camera", "sensor", "gpio", "wifi", "raspberry"]),
]


def seed(value=42):
    torch.manual_seed(value)
    torch.set_num_threads(1)


def records():
    """One group per topic keyword; all paraphrases stay in the same split."""
    rows = []
    for label, words in GROUPS:
        for i, word in enumerate(words):
            split = "train" if i < 4 else "validation" if i == 4 else "test"
            for template in ["help with {}", "please explain {}", "debug my {}"]:
                rows.append(
                    dict(
                        text=template.format(word),
                        label=label,
                        group=f"{label}-{word}",
                        split=split,
                    )
                )
    return rows


def tokens(text):
    return re.findall("[a-z0-9]+", text.lower())


def make_vocab(rows):
    return {
        word: i
        for i, word in enumerate(sorted({w for r in rows for w in tokens(r["text"])}))
    }


def encode(rows, vocab):
    x = torch.zeros(len(rows), len(vocab))
    for i, row in enumerate(rows):
        for word in tokens(row["text"]):
            if word in vocab:
                x[i, vocab[word]] += 1
    return (x, torch.tensor([LABELS.index(r["label"]) for r in rows]))


class Router(nn.Module):
    def __init__(self, width, hidden=16):
        super().__init__()
        self.encoder = nn.Linear(width, hidden)
        self.head = nn.Linear(hidden, 3)

    def forward(self, x):
        return self.head(torch.tanh(self.encoder(x)))


class LoRALinear(nn.Module):
    def __init__(self, base, rank=2, alpha=2):
        super().__init__()
        self.base = copy.deepcopy(base).requires_grad_(False)
        self.A = nn.Parameter(torch.randn(rank, base.in_features) * 0.02)
        self.B = nn.Parameter(torch.zeros(base.out_features, rank))
        self.scale = alpha / rank

    def forward(self, x):
        return self.base(x) + x @ self.A.T @ self.B.T * self.scale

    def merged_weight(self):
        return self.base.weight + self.scale * self.B @ self.A


def train(model, x, y, steps=100, lr=0.03):
    params = [p for p in model.parameters() if p.requires_grad]
    optimizer = torch.optim.Adam(params, lr=lr)
    losses = []
    model.train()
    for _ in range(steps):
        optimizer.zero_grad(set_to_none=True)
        loss = F.cross_entropy(model(x), y)
        loss.backward()
        optimizer.step()
        losses.append(float(loss.detach()))
    return losses


def prepare():
    """Pretrain on an explicitly separate, synthetic source corpus."""
    seed()
    target = records()
    source = []
    for label, words in GROUPS:
        for word in words:
            source.append(dict(text=f"general guide {word}", label=label))
    vocab = make_vocab(source + [r for r in target if r["split"] == "train"])
    sx, sy = encode(source, vocab)
    base = Router(len(vocab))
    train(base, sx, sy, steps=45, lr=0.02)
    return (base, vocab, target)


def method(base, name):
    model = copy.deepcopy(base)
    model.requires_grad_(False)
    model.encoder = LoRALinear(base.encoder, rank=2, alpha=2)
    return model


def counts(model):
    return {
        "trainable": sum((p.numel() for p in model.parameters() if p.requires_grad)),
        "total": sum((p.numel() for p in model.parameters())),
    }


def main():
    import torch

    W = torch.eye(2)
    A = torch.tensor([[1.0, 2.0]])
    B = torch.tensor([[0.1], [0.2]])
    x = torch.tensor([[2.0, 1.0]])
    separate = x @ W.T + x @ A.T @ B.T
    merged = x @ (W + B @ A).T
    print("delta W:", B @ A, "output:", separate)
    assert torch.allclose(separate, torch.tensor([[2.4, 1.8]]))
    assert torch.allclose(separate, merged)
    base, vocab, rows = prepare()
    x, y = encode([r for r in rows if r["split"] == "train"], vocab)
    model = method(base, "lora")
    assert torch.allclose(model(x), base(x))
    frozen = model.encoder.base.weight.detach().clone()
    history = train(model, x, y, steps=100, lr=0.02)
    assert torch.equal(frozen, model.encoder.base.weight)
    with torch.no_grad():
        separate = model.encoder(x)
        merged = torch.nn.functional.linear(
            x, model.encoder.merged_weight(), model.encoder.base.bias
        )
    assert torch.allclose(separate, merged, atol=1e-05)
    print(counts(model), "merge max error:", float((separate - merged).abs().max()))


if __name__ == "__main__":
    main()
Run it and compare the result
Run commands from the lesson folder. In the commands below, python means the environment you installed into. On Windows, substitute .venv\Scripts\python.exe; on Linux/macOS substitute .venv/bin/python. Do not create the environment with one interpreter and run the lesson with another.
Run 1: python lesson.py
python lesson.py
Captured standard output:
delta W: tensor([[0.1000, 0.2000],
        [0.2000, 0.4000]]) output: tensor([[2.4000, 1.8000]])
{'trainable': 84, 'total': 567} merge max error: 2.384185791015625e-07
The displayed output was captured from the supplied default program in a separate folder, with no project-level module on its import path. It is a reproducible demonstration on these examples, not a claim about arbitrary inputs.
Walk through what just happened
1. Verify the small multiplication
The identity base and rank-one correction produce [2.4, 1.8] for input [2, 1]. The first assertion establishes the arithmetic used by the explanation.
2. Wrap an existing layer
LoRALinear freezes a copy of the original layer, initializes A randomly and B to zero, and scales the correction by alpha/rank.
3. Train only the new values
The optimizer receives parameters whose requires_grad flag is True. The frozen-weight equality assertion checks that the base matrix did not move.
4. Prove the merge
merged_weight adds the learned matrix correction to the float base. allclose verifies that the separate and merged calculations differ only within a small numeric tolerance.
Change one thing yourself
Use input width 6, output width 4, and rank 2 to calculate A’s shape, B’s shape, and the correction shape before editing the model.
If your result is different
Do not initialize both factors to zero: this multiplication then starts with zero gradients for both. Also distinguish ordinary float merging from specialized quantized deployment.
Check the complete imports and filenames first. Then compare your input and command with the shown run. Numeric results may differ slightly between platforms; the program's assertions check the intended relationships rather than relying on a decorative screenshot.
What you can now explain
Calculate, train, and merge a low-rank weight correction. Next we will build on this result in Part 6.
Technical reference: PyTorch learning basics. This project and its wording are original CodeTips Academy material.


